Practical decisions for AI and software
Technical guides to choose models, verify software and plan delivery.
Search every article
Search the full article text.
No posts match your search. Try another term or pick a topic.
Latest articles
New comparisons, practical guides and engineering lessons.
 Delivery & QA
AgentMail for SaaS: Tenant Isolation and Duplicate-Send Recovery
Design AgentMail email workflows with tenant-scoped keys, durable send intents and recovery after lost responses. Includes a proposed failure-test matrix.

 Product & MVP
Scope vs Armature: Measure Agent API Adoption Beyond Mentions
Compare Scope and Armature for agent discovery and API usability. Evaluate installation, authentication and completed tasks with a proposed buying checklist.
 Delivery & QA
Browser Use vs Playwright: Verify Authenticated Actions After Timeouts
Choose Browser Use or Playwright for authenticated workflows. Handle saved login state, uncertain submissions and retries with independent acceptance checks.
 AI & Agents
OpenAI Decisions API: Confidence, Refusals and Routing
A public-beta routing guide with a real request shape, per-question refusal handling, probability thresholds and a worked input-cost example.
 AI & Agents
Claude Model Router: What Switches the Model, and When?
A model recommendation can leave your active session unchanged. Compare native controls, model-router hooks and provider gateways, then verify what actually runs.
 Delivery & QA
AI Coding and the Software Moat: Who Runs What You Build?
AI makes more custom software worth building. The next decision is who runs it. Compare build, buy and hybrid options through cost, reliability and ownership.
 AI & Agents
Cloudflare Clef vs Jev: Pricing, Benchmarks and Migration
Clef brings open weights and vision to the Jev-style decision API. But price, confidence semantics and Flash results make migration less simple than it looks.
 AI & Agents
Context Language Models vs Compaction: What to Pilot
Should your agent edit its own context? Compare CLMs with compaction, inspect the real harness and license, and test what happens when essential facts disappear.
 AI & Agents
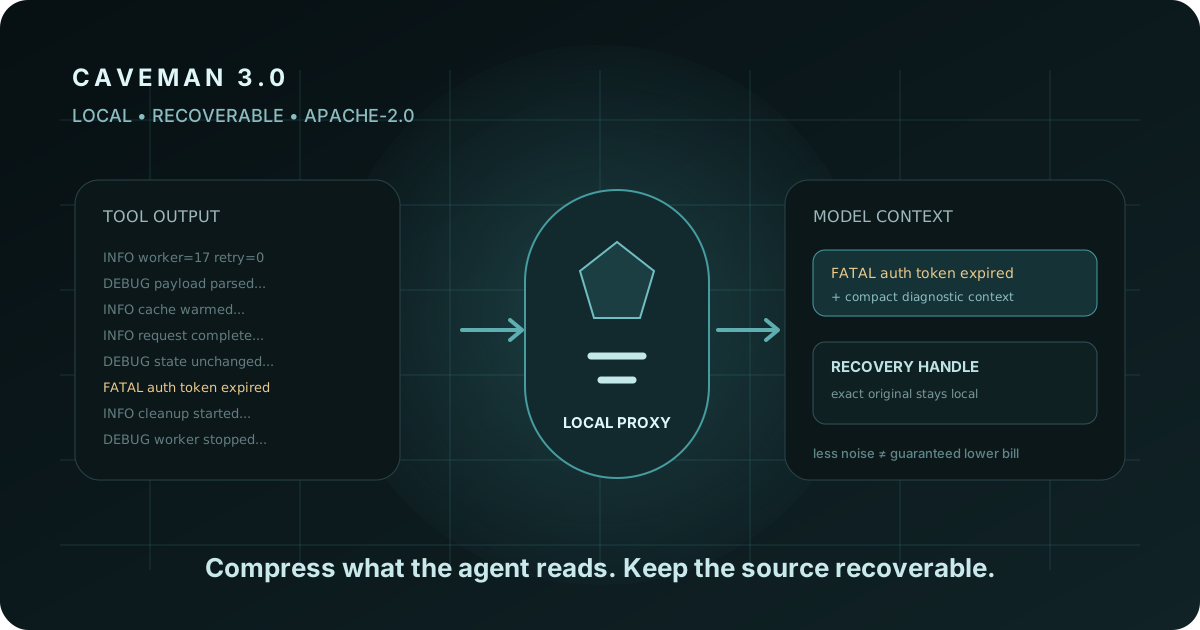
Caveman 3.0 for Claude Code: Local Input Compression, Recovery and Benchmarks
Caveman 3.0 puts an Apache-2.0 compression layer between coding agents and models. Here is what its proxy, recovery path, Learn profiler and 33.2% input-token benchmark actually prove.
Get the next field note
One concise email when we publish. No tracking pixels, and no inbox filler.