Models and infrastructure
Model selection, inference economics, local deployment, compression and serving architecture.
- Blog posts
- 80
- Topic
- AI and agents
Start here
Latest in this collection
 AI & Agents
Cue Turn Detection: Phone Numbers, Benchmarks and Limits
A pause is not a finished phone number. What Pype’s Cue v1 improves, what the benchmarks measure, and how to test correct, confirmed capture.
 AI & Agents
Google SAM is now Agent Mesh: MCP tools across machines
Connect approved tools across machines. Understand the control plane, signed EU labels and the checks a useful first pilot should pass.
 AI & Agents
EdgeQuake: PostgreSQL GraphRAG for MCP agent memory
Connect document relationships to your agents. A v0.34.0 review of PostgreSQL deployment, MCP access, local model roles and the LightRAG benchmark.
 AI & Agents
BitNet on CPU: 2B4T, real RAM needs and the 100B claim
Which BitNet model can you download, and what fits your CPU? Separate the 100B benchmark, 0.4 GB metric and 1.19 GB file, then test a real task.
 AI & Agents
SuperPenguin: AI Cost per PR, Customer and Feature
What did a merged PR cost, and what does each customer cost to serve? A practical SuperPenguin guide with billing reconciliation, worked examples and an optimization prompt.
 AI & Agents
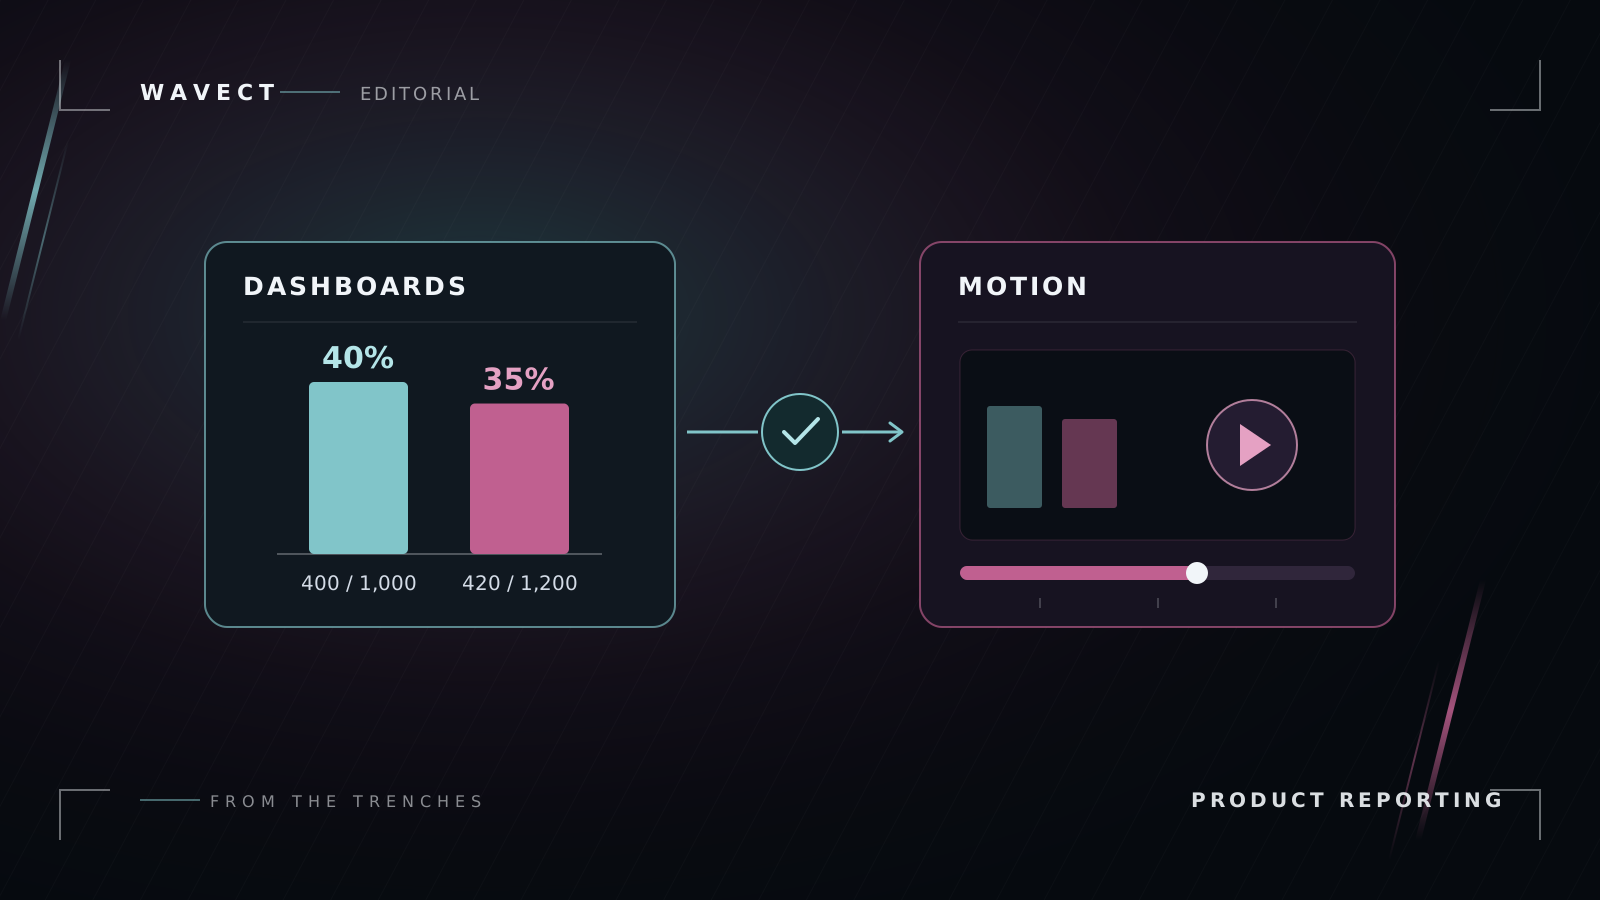
Claude Dashboards + Motion: From KPIs to Video
Turn a reviewed product metric into a short animated update. A practical Claude Dashboards and Motion workflow with a cohort example, two prompts and sharing rules.
Complete article directory
- Cue Turn Detection: Phone Numbers, Benchmarks and Limits
- Google SAM is now Agent Mesh: MCP tools across machines
- EdgeQuake: PostgreSQL GraphRAG for MCP agent memory
- BitNet on CPU: 2B4T, real RAM needs and the 100B claim
- SuperPenguin: AI Cost per PR, Customer and Feature
- Claude Dashboards + Motion: From KPIs to Video
- OpenAI Intelligent UI vs OpenUI: Generative UI for Business Apps
- Wally by RunAnywhere: Cost per Accepted Coding Task
- Reducto for German Invoices: Measure Human Review Effort
- OpenAI Decisions API: Confidence, Refusals and Routing
- Claude Model Router: What Switches the Model, and When?
- Cloudflare Clef vs Jev: Pricing, Benchmarks and Migration
- Context Language Models vs Compaction: What to Pilot
- Caveman 3.0 for Claude Code: Local Input Compression, Recovery and Benchmarks
- LiteLLM Lens: Agent Trace Analysis with SQL and APIs
- SmythOS Studio Self-Hosting: Docker Setup, Costs and Limits
- DeerFlow 2.0: Docker Setup, Sandboxes and Memory
- CLM-8B Self-Hosting: vLLM, Action Cache and Verifiers
- AnyJev: LLM Calibration and Option-Order Bias
- LiteAgents SDK: Per-Turn Routing, Setup and Migration
- mcp-memory-service: Shared Memory for Claude Code and Cursor
- Claude Opus 5.5: Best Uses, Prompts and Effort Settings
- Laya and Jev for Business: 6 Practical Workflows
- Laya vs Jev: What the Benchmarks Mean for AI Startups
- Jev AI Review: Decision Models for Agent Workflows
- SwarmLLM Review 2026: Browser P2P LLM Inference Across Phones and Laptops
- Phonely Alma Review: Is the Voice LLM Ready for Production?
- Utopia Review: Temporal Knowledge Graph for Enterprise
- NVIDIA PAIR Review: Local AI Routing and the AMD Gap
- Tencent Hy4 Preview Review: Is the 1M-Context Coding Model Worth a Pilot?
- PageLM Review: Self-Hosting and Commercial Use
- M6 Mac mini vs M5 Mac Studio for Local AI: Buyer's Guide
- FreeToken AI Review: Run Frontier MoE Models on Consumer GPUs?
- Darkbloom AI Review: Private Inference on Idle Macs
- Ox Alpha Revealed as GLM-5.3-Flash: What Changed
- Pika Audio Models API Pricing: Is SFX Really 20x Cheaper?
- Thunder Compute's $13M GPU Virtualization Bet: Enterprise Buyer's Guide
- AirLLM on 4 GB VRAM: How Layer-Wise Inference Really Works
- Qwen3.8-27B: Self-Hosted Computer-Use Agents Without Exporting Screenshots
- Netflix's vLLM and Triton Stack: 7 Production Lessons
- Transformers.js Browser AI: When Local Inference Belongs in Your Product
- How to Self-Host LiteLLM in Production: 2026 Guide
- AI-Ready Company Wiki: Architecture and Build Guide
- Does Claude Watermark Text? The 2026 API Answer
- OpenKB Review: Knowledge Compiler vs RAG
- Unsloth Desktop Review: A Private Local AI Workstation?
- NeMo Switchyard 0.2: Agent Model Routing Without Training?
- Firecrawl AnyDoc Review: 14 Formats to Markdown
- Muse Glimmer 30B: Is Meta's Local Agent Model Production-Ready?
- OmniRoute AI Routing: Setup and Production Checklist
- Gemini Robotics 2: Whole-Body Control and the Pilot Decision
- pdf-inspector Review: Route PDFs Before OCR
- Local Multimodal AI Coding Assistant: Voice, OCR and Privacy
- DeepSeek V4 Flash 0731 on One AI PC: What Actually Works?
- Fine-Tune Gemma 4 Free with Unsloth and Colab
- Taalas HC1 Review: Is a Hardwired LLM ASIC Worth It?
- llmfit Guide: Which Local LLM Fits Your Hardware?
- Miso TTS Self-Hosted vs API: Cost, Latency and VRAM Reality
- Compress RAG Vectors to 2 Bits: Is Data-Oblivious Quantization Production-Ready?
- LMCache Reported 13.7x Lower Mean TTFT with a Shared KV Cache
- Lossless LLM Weight Compression vs 8-bit GGUF: What Is Ready for Production?
- NVIDIA Nemotron 3.5 ASR: Is Free Self-Hosted STT Ready for Voice Agents?
- Kimi K3 for EU Companies: API Cost, Data Risk, and a Pilot Plan
- Mesh LLM Review: Can One Large LLM Run Across Multiple Computers?
- Bonsai 27B Review: Can a 27B LLM Really Run on a Phone?
- Soofi S: Is Germany's Sovereign LLM Ready for Business?
- Colibri Runs GLM-5.2 on Consumer Hardware. Here Is the Catch.
- When Local Models Beat APIs: A Break-Even Calculator for EU Companies
- LLM Cost Calculator 2026: Cost per Task, Not Cost per Token
- Pxpipe Review: Can Images Cut Claude Code Token Costs 60%?
- Cheaper Per Token Can Still Cost More Per Task
- Anthropic Says No Open-Weights Ban. The Cost War Is Still Real.
- What an Internal AI Assistant Actually Costs in the DACH Region (2026)
- LLM Gateways Compared 2026: LiteLLM vs OpenRouter vs Portkey vs RouteLLM
- Self-Hosting LLMs in the EU: When Open Weights Actually Pay Off
- Open-Weight LLMs 2026: DeepSeek, Qwen, Kimi, GLM, Llama and Muse
- How to Cut LLM Token Costs in 2026
- When Is an LLM Eval Worth Building? Cost, ROI, and Trusting the Judge
- RAG vs Fine-Tuning vs Long-Context 2026
- LLM API Costs 2026. Architecture Shift
Get the next AI and agents field note
One concise email when we publish. No tracking pixels, and no inbox filler.